NeurIPS 2026

SkillForge: Co-Evolving Skills and Agents via Dynamic Skill Lifecycles

A skill library should not only grow. Mutation children enter as trial, seed skills that survive pre-retirement start as active or stable, and anything the improved policy outgrows is demoted, rewritten or retired.

Yuyao Ge1, Yiwei Wang2, Yuchen He1, Baolong Bi1, Lingrui Mei1, Jiayu Yao1, Lizhe Chen3, Shenghua Liu1,†
1Institute of Computing Technology, Chinese Academy of Sciences
2University of California, Merced  ·  3Tsinghua University
† Corresponding author
The one-library story

Same policy. Same tasks.
One library is archived. The other is forged.

On ALFWorld the append-only library grows past 130 skills and still loses to a compact one of 100. SkillForge retires 32 of them and generates 88 mutations, 57 of which survive.

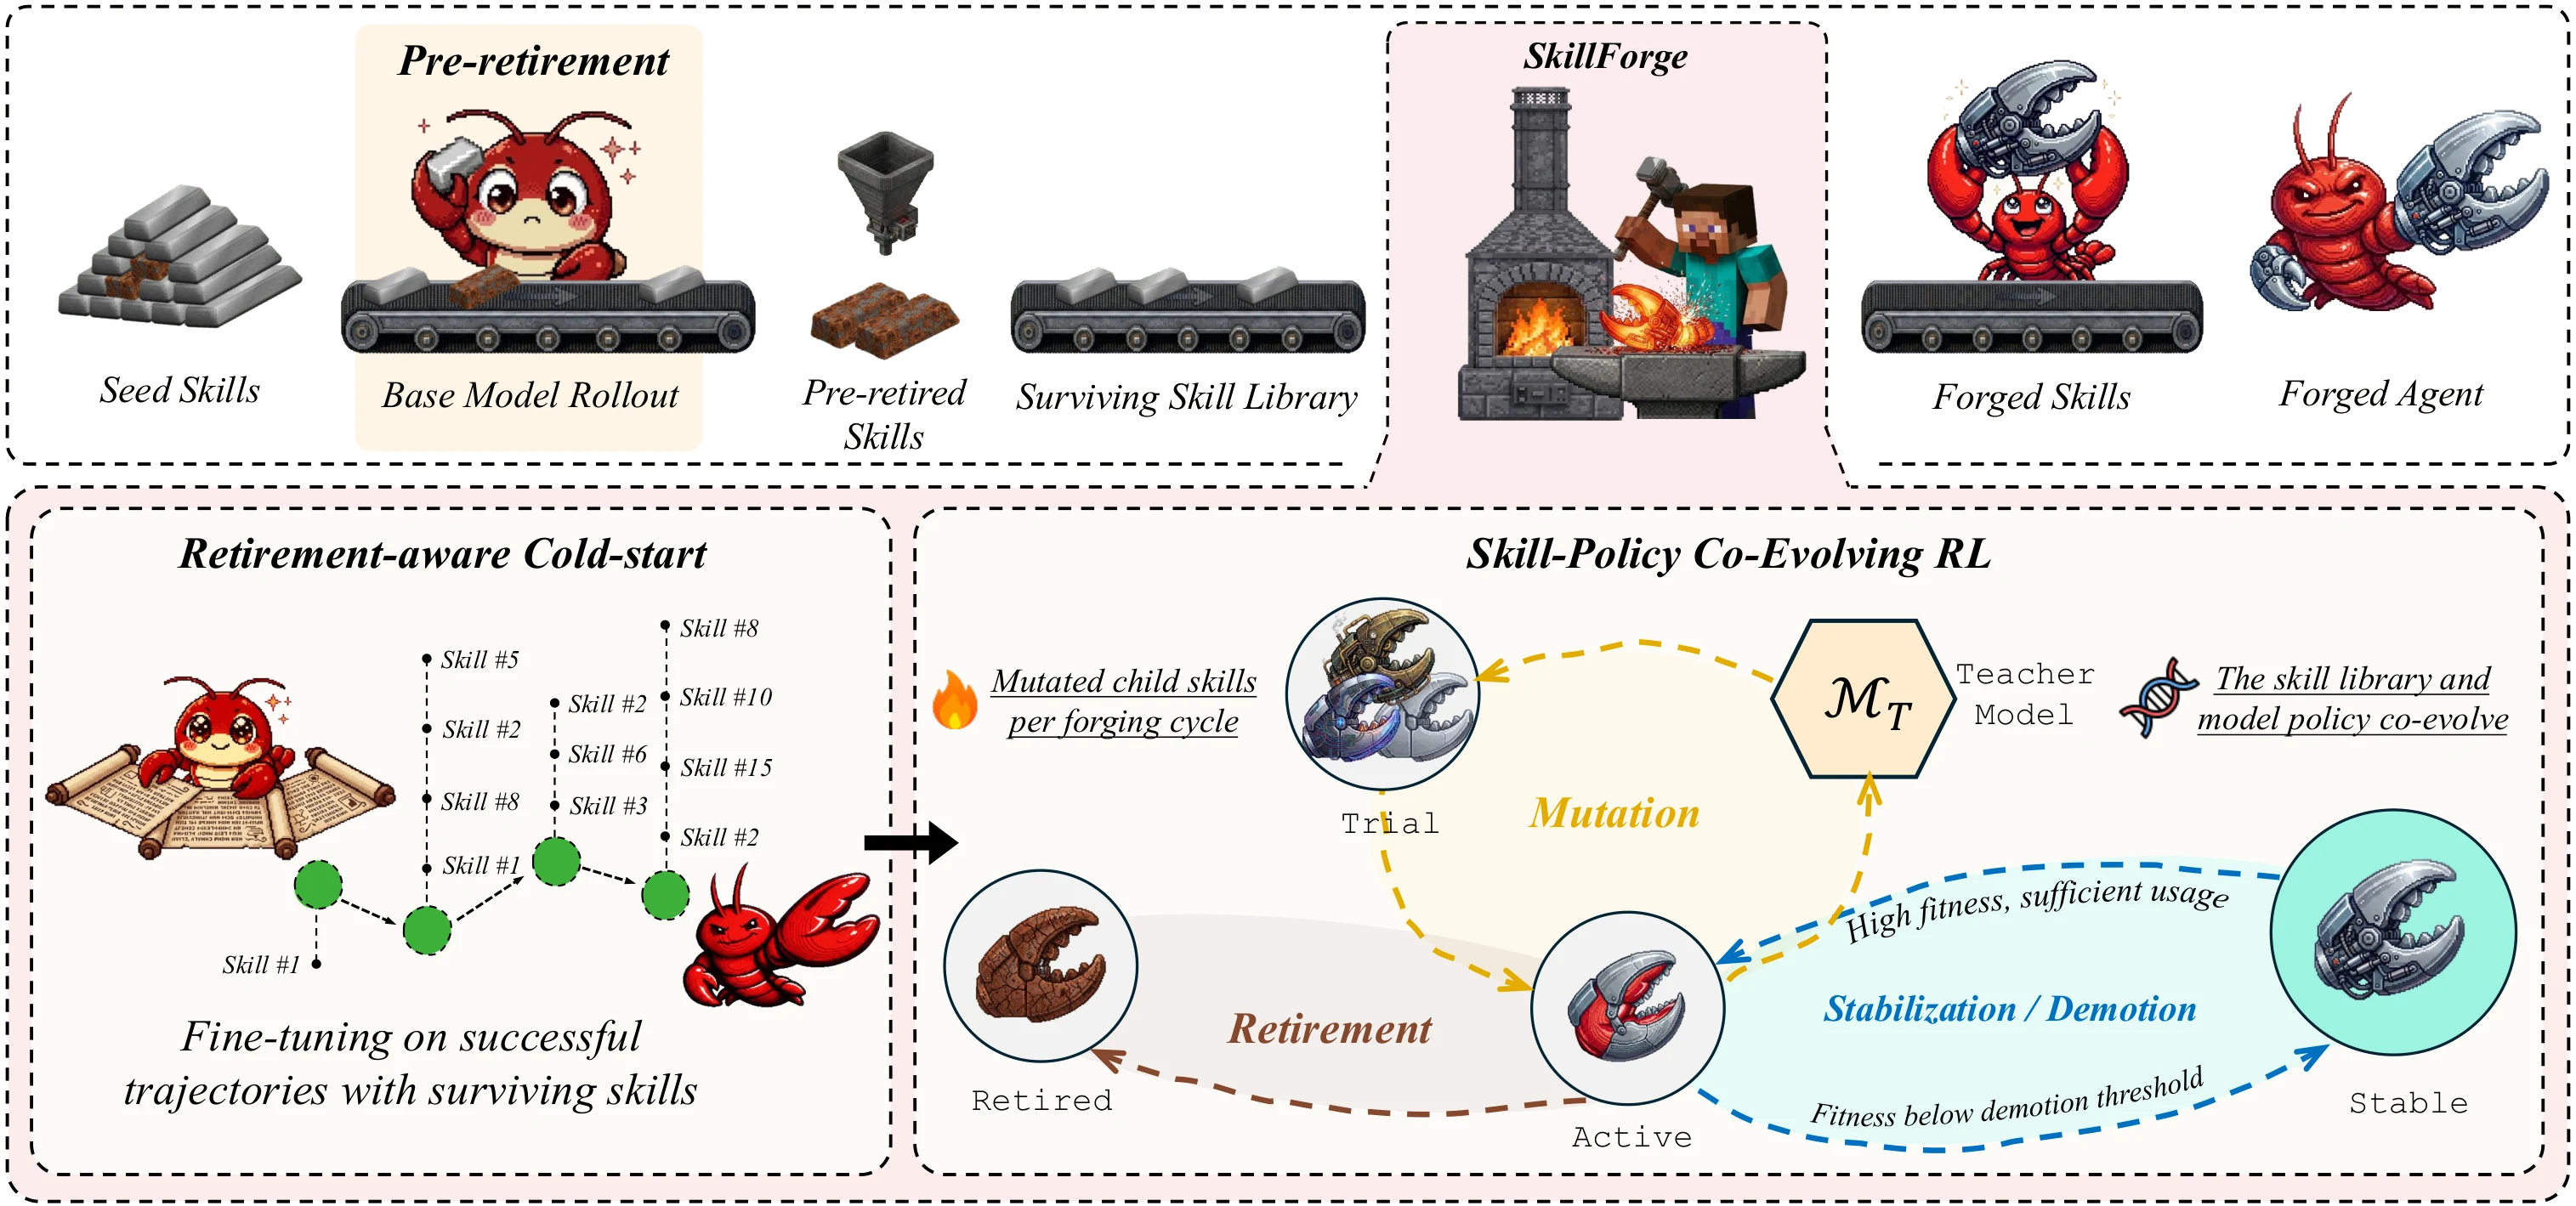
SkillForge overview: seed skills are pre-retired under base-model rollouts, survivors seed retirement-aware cold-start, and skills co-evolve with the policy through trial, active, stable and retired states.

Pre-retire the seed library under the base model, warm up on what survives, then let skills and policy co-evolve through trial → active → stable → retired.

§1 · The problem

A skill library does not rot because the skills were bad.

Every method in this family keeps the library append-only. A skill that was correct at step 20 encodes a procedure the model has outgrown by step 120 — and it is still being retrieved into the context, still phrased as an instruction.

Delayed obsolescence · the event the lifecycle exists to catch
$$\exists\, k_1 < k_2:\quad f_i^{(k_1)} \ge \delta_{\text{stable}} \;\wedge\; f_i^{(k_2)} < \delta_{\text{retire}}$$
0
Avg. peak fitness of a retired skill · vs. δstable = 0.7
0
Avg. fitness drop from that peak to retirement
0
Of retired skills reached stable before decaying
0
Of retirements caused by overly rigid ordering
§2 · The lifecycle

Four states, five moves, one hysteresis band.

Each skill carries a fitness fi = Ci / Ui and a usage count Ui. Active is the hub — nothing leaves the library without passing through it. Hover a state or an arrow.

mutate promote stabilize demote retire TRIAL ACTIVE STABLE RETIRED
stable active trial retired mutated total non-retired
retired mutation band stabilized 0.00 1.00 0.4 0.5 0.7
Delayed obsolescence · the definition, drawn
δ stable 0.7 δ retire 0.4 k₁ · stabilizes k₂ · retires training step
Retire · 0.4Actives below this are removed, once used 20 times.
Demote · 0.5A stable skill must fall past this to be retirable.
Mutate · 0.4–0.7Parents sampled with P ∝ 1 − f.
Stabilize · 0.7Actives above this with 30 uses gain protection.
Lifecycle update rule · applied once per forging cycle
$$\ell(s_i) \leftarrow \begin{cases} \texttt{active} & \ell = \texttt{trial} \;\wedge\; U_i \ge N_{\text{promote}}\\[2pt] \texttt{stable} & \ell = \texttt{active} \;\wedge\; f_i \ge \delta_{\text{stable}} \;\wedge\; U_i \ge N_{\text{stable}}\\[2pt] \texttt{active} & \ell = \texttt{stable} \;\wedge\; f_i < \delta_{\text{demote}}\\[2pt] \texttt{retired} & \ell = \texttt{active} \;\wedge\; f_i < \delta_{\text{retire}} \;\wedge\; U_i \ge N_{\text{retire}}^{(g_i)} \end{cases}$$
§3 · The method

Pre-retire, cold-start, then co-evolve.

Seed library44 / 66 / 41 skills per environment
→
i · Pre-retireRoll out the base model, drop f < 0.3
→
ii · Cold startSFT on the surviving trajectories
→
iii · Co-evolveGRPO + the lifecycle, every 10 steps
→
AgentPolicy and library, co-evolved
every 10 steps PROMOTE U ≥ 10 DEMOTE f < 0.5 RETIRE f < 0.4 STABILIZE f ≥ 0.7 MUTATE P ∝ 1 − f
“Pick Before You Wander”
g0f = 0.84
teacher rewrites it from its own failures · Kimi-K2.5
“Verify, Grab, and Confirm Pickup”
g1f = 0.70stable
“Retrieve Target Before Locating Desklamp”
g1f = 0.24retired

One parent, two children: the variant that adds a verification step stabilizes, the one that imposes a fixed ordering is retired at step 65. The lifecycle keeps the first and drops the second.

Mutation · a child enters the library as trial, one generation deeper
$$s_{\text{child}} = \mathcal{M}_T\big(\mathcal{P}_\mu(s_{\text{parent}},\, f_{\text{parent}},\, \mathcal{T}_{\text{fail}})\big)$$
§4 · Results

Compact, not bigger — and better on every environment.

ALFWorld, WebShop and Search-Augmented QA. SkillForge beats the strongest memory-augmented RL baseline on all three, and the closed-source GPT-4o / Gemini-2.5-Pro references by a wide margin on the agentic environments.

ALFWorld · validation success

All four series of the paper's Fig. 3(b). SkillForge separates from SkillRL after step 75 and holds near 90% while SkillRL oscillates in the 80–88% band; both stay well clear of the two GRPO variants.

Search-Augmented QA · per dataset

Seven datasets over the same 51,713-sample union. SkillForge is best or second-best on every axis; the largest gains over the strongest baseline are on Bamboogle (+3.4) and HotpotQA (+0.7).

0
ALFWorld success · vs. 89.9% for SkillRL
0
WebShop success · +7.8% relative over SkillRL
0
Search-Aug. QA · micro-average over 51,713 samples
0
Largest subtask gain · ALFWorld Look, relative

Baselines SkillForge
§5 · Case studies

One parent, two children, opposite verdicts.

Mutation explores both directions from the same parent. The surviving child often has a lower aggregate fitness, because it targets a narrower niche — the lifecycle scores within-niche accuracy, not popularity.

Citation

Cite SkillForge

@misc{ge2026skillforgecoevolvingskillsagents,
      title={SkillForge: Co-Evolving Skills and Agents via Dynamic Skill Lifecycles},
      author={Yuyao Ge and Yiwei Wang and Yuchen He and Baolong Bi and
              Lingrui Mei and Jiayu Yao and Lizhe Chen and Shenghua Liu},
      year={2026},
      eprint={2610.09832},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2610.09832},
}